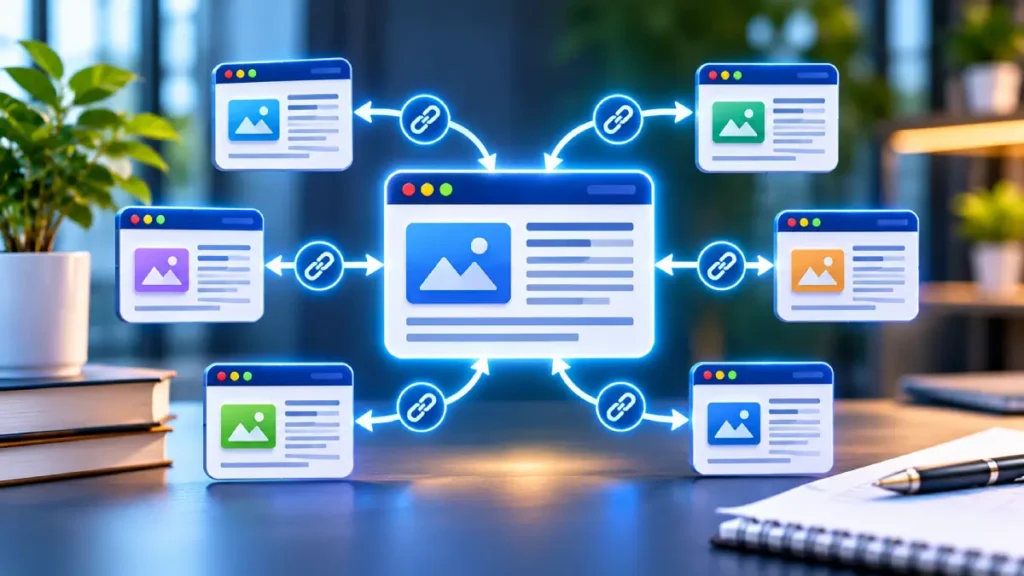
Internal linking is the practice of hyperlinking one page on a domain to another page on the same domain, serving as the foundational plumbing for PageRank distribution, crawl budget efficiency, and semantic topical authority.
Unlike external backlinks, internal links remain entirely within your architectural control, allowing you to manipulate anchor text relevance, establish rigid parent-child content silos, and compress click-depth for high-priority commercial and informational assets.
For SEO professionals, mastering internal linking goes beyond dropping random contextual links; it requires engineering a mathematically sound graph structure that guides search engine spiders, passes link equity seamlessly, and resolves orphan page liabilities across enterprise architectures.
The Mechanics of Link Equity Distribution & PageRank Flow
Search engine crawlers evaluate link equity not merely as a binary vote, but as a continuous flow of probabilistic authority through a directed graph, a concept originally modeled in the Stanford PageRank algorithm paper.
Every page on your domain possesses a cumulative PageRank score derived from incoming internal and external links, aligned with official Google Search Central guidelines on link optimization.
When you place an internal link within the body of a high-authority document, you distribute a fraction of that equity to the target URL. However, unoptimized architectures frequently suffer from severe equity leakage.
- Damping Factors & Link Dilution: As navigation menus, footers, and sidebars duplicate identical internal links across thousands of templates, the relative equity passed per link diminishes. Global site-wide links dilute contextual PageRank, whereas in-content contextual links carry significantly higher algorithmic weight.
- Orphan Page Elimination: Pages with zero internal pointing links become virtually invisible to crawlers, relying solely on XML sitemaps for discovery. Regular log file audits and link graph crawls are mandatory to identify and anchor orphan URLs into relevant thematic hubs.
- Click-Depth Compression: High-value conversion pages should ideally reside within two to three clicks from the homepage. Deeply buried URLs experience diminished crawl frequency and lower ranking velocity due to weaker PageRank accumulation.
Semantic Topical Authority and Content Silo Architecture
Modern search algorithms rely heavily on vector embeddings and natural language understanding models—such as those introduced in Google’s BERT language model documentation—to extract semantic entities and determine how subtopics relate to a core parent theme.
Randomly linking disparate articles creates a flat, unstructured information architecture that confuses search engine crawlers regarding topical boundaries.
Rigid content siloing resolves this by establishing hierarchical relationships between pillar pages and supporting cluster content. Within a strict silo:
- Pillar-to-Cluster Linking: The overarching pillar page links downward to every specific subtopic article, establishing primary topical relevance.
- Cluster-to-Pillar Linking: Every supporting article links upward back to the parent pillar, reinforcing the hierarchical anchor.
- Lateral Cluster Linking: Related subtopic articles cross-link horizontally where natural semantic bridges exist, strengthening the local entity cluster without breaking thematic boundaries.
This interconnected web signals to search engine algorithms that your domain possesses comprehensive topical depth and authoritative coverage across the entire subject matter domain, directly supporting broader topical authority frameworks.
Advanced Anchor Text Optimization & Semantic Variance
Anchor text serves as the primary textual descriptor signaling the subject matter of the destination URL. However, aggressive over-optimization—such as repeating exact-match commercial anchor texts across hundreds of internal links—can trigger algorithmic suspicion or cannibalization filters.
| Anchor Text Strategy | Risk Level | Recommended Use Case | Algorithmic Impact |
| Exact Match | Moderate | Primary pillar pages with precise semantic intent | High topical reinforcement; risk of over-optimization if overused. |
| Partial Match | Low | Supporting cluster articles and secondary variations | Safe, natural distribution; broadens semantic relevance. |
| Branded / Contextual | Zero | Natural sentence integration | Zero penalty risk; provides natural reading flow. |
To maintain a natural link profile, SEO professionals should prioritize semantic variance. Instead of forcing repetitive keywords, incorporate natural sentence structures that describe the value of the target page explicitly, allowing search engines to infer context through surrounding sentence vectors.
Crawl Budget Optimization and Indexation Priority
For enterprise websites containing millions of dynamic URLs, crawl budget is a finite resource. As detailed in the Google Search Central crawl budget guide for large sites, search engine bots allocate a specific crawl allowance based on site popularity, host capacity, and server response health.
Inefficient internal linking structures can severely waste crawl budget on low-value filter pages, parameter URLs, or outdated archives.
- Managing Crawler Traps: Prevent infinite redirection loops and low-value parameterized pagination from draining crawl capacity by routing internal links away from non-indexable states.
- Prioritizing Fresh Content: Ensure newly published or updated articles receive immediate internal links from high-traffic, frequently crawled hub pages to accelerate discovery and indexation.
- Orchestrating XML Integration: Align your internal linking graph with your XML sitemap strategy to ensure that crawl paths mirror indexation priorities. For advanced technical optimizations regarding crawl efficiency, review resources available.
Data-Driven Internal Linking Frameworks & Automation Audits
Manual internal linking breaks down at scale. Enterprise SEO demands data-driven frameworks that leverage vector embeddings, natural language processing (NLP), and log file analysis to surface contextual linking opportunities programmatically.
- Semantic Similarity Matching: Utilizing Python-based vector embeddings (such as BERT or OpenAI embeddings) against your site corpus allows you to compute cosine similarity scores between articles. High similarity scores paired with zero existing internal links highlight immediate contextual linking opportunities.
- Log File Intersections: Cross-referencing server log files with crawler reports exposes pages receiving heavy crawler hits versus pages being ignored, allowing you to redirect internal link equity toward neglected revenue-generating assets.
- Continuous Monitoring: Implement automated link-integrity scripts that flag broken internal redirects, redirect chains, or removed anchor targets before they degrade user experience and equity flow.